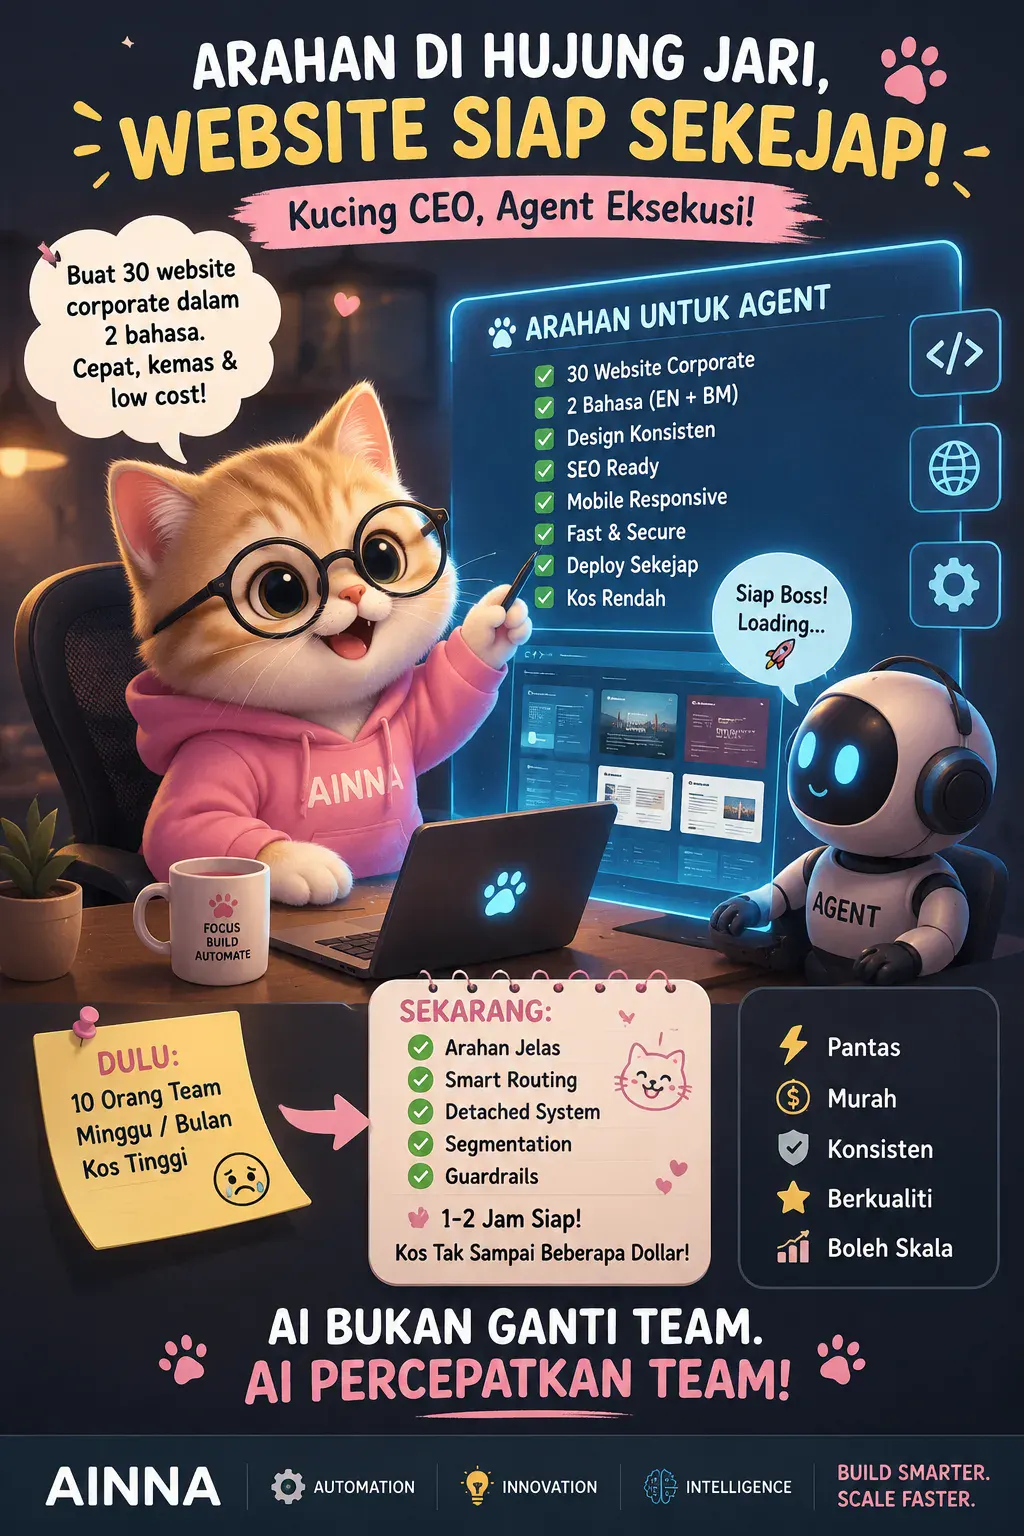
In the field, deploying 30 corporate websites in two languages used to mean standing up a team of nearly 10 people: developers, designers, translators, content writers, SEO specialists, QA testers and project managers. The timeline stretched across weeks or months, and the real cost often showed up later in maintenance and rework.
Today, with a properly wired pipeline, the same scope can ship in about one or two hours. The inference and processing bill can stay under a few dollars. The key is not sending every task to a large LLM; it is building the workflow so each layer uses the cheapest, most reliable component that can handle the job.
The first layer is Smart Routing. I let deterministic scripts, templates, rules and lightweight models take care of file checking, text replacement, validation and repetitive updates. The heavy generative models only get invoked for work that actually needs reasoning, language context or quality review.
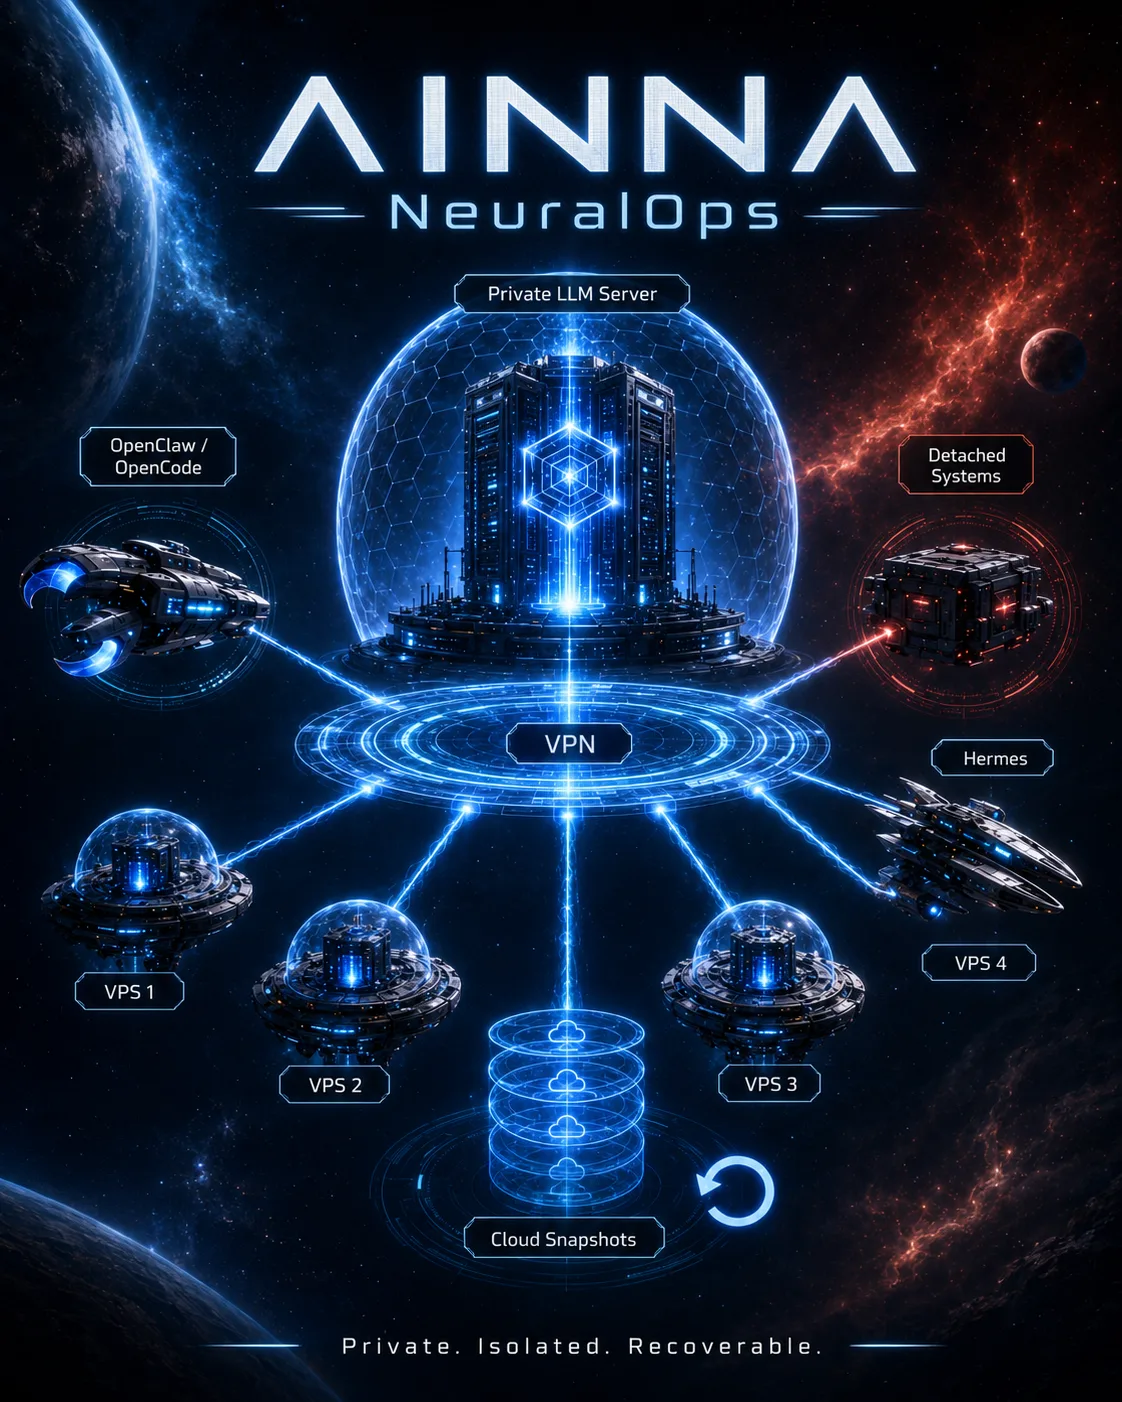
The second principle is the Detached System. Server-side rendering, DNS/domain mapping, syntax checks, SEO validation and deployment smoke tests run outside the AI inference path. That keeps costs predictable, removes a single point of failure and makes rollback clean when a node misbehaves.
The third principle is Segmentation. I split the build into discrete stages-audit, extraction, translation, implementation, testing and reporting. Each stage gets a strict input schema, output artifact and pass/fail gate, so the pipeline stays observable, debuggable and improvable without tearing down the whole stack.
Finally, strong Guardrails are non-negotiable. Translation keys, fallback rules, protected terminology lists, JSON/schema validation, syntax tests and mandatory human approval keep hallucinated or malformed output out of production. The real advantage is not the model itself; it is the architecture you wrap around it.
#ArtificialIntelligence #Automation #SmartRouting #DetachedSystem #Segmentation #Guardrails #WebDevelopment #DigitalTransformation #AINNA #NeuralOps
Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
إذا كان هناك جزء آخر عن 10 فسأقرأه.
Worth reading for output artifact and pass/fail gate alone.
deploying 30 corporate websites - that is the whole thing in one line.
The part on language context or quality review is the bit I keep re-reading.
Terus terang, 10 ni menarik.