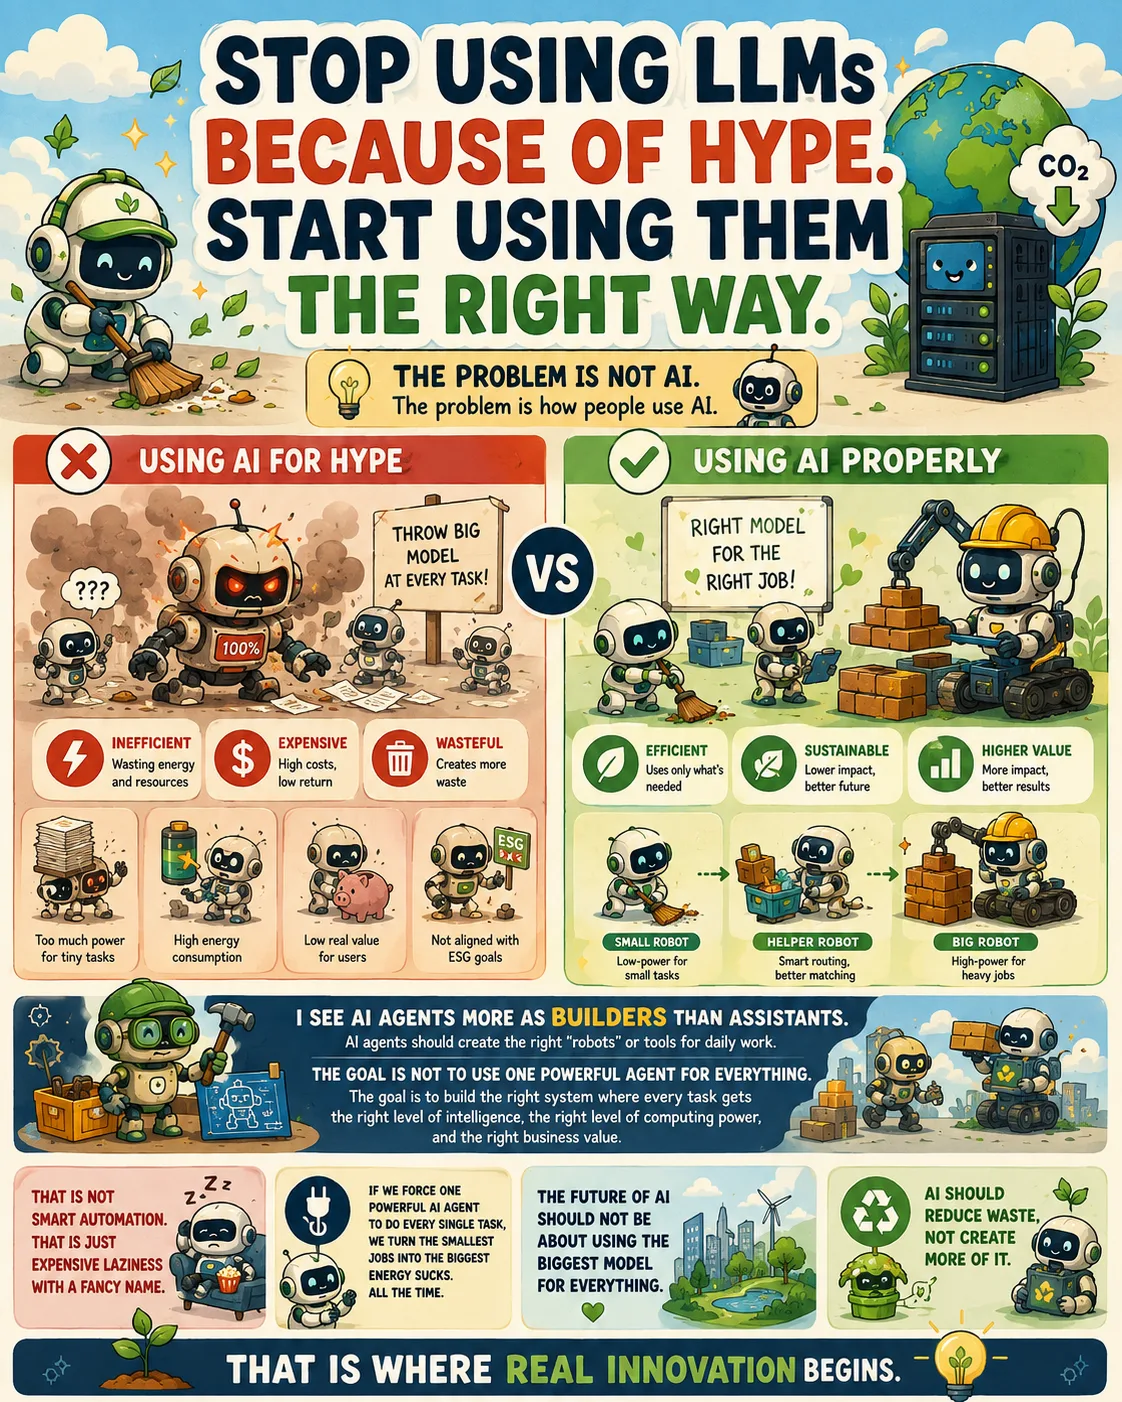
In fact, it drives up carbon footprints, inflates cloud bills, adds operational debt, and leaves end users with little to show for it.
The issue is not the models themselves.
The issue is how we architect around them.
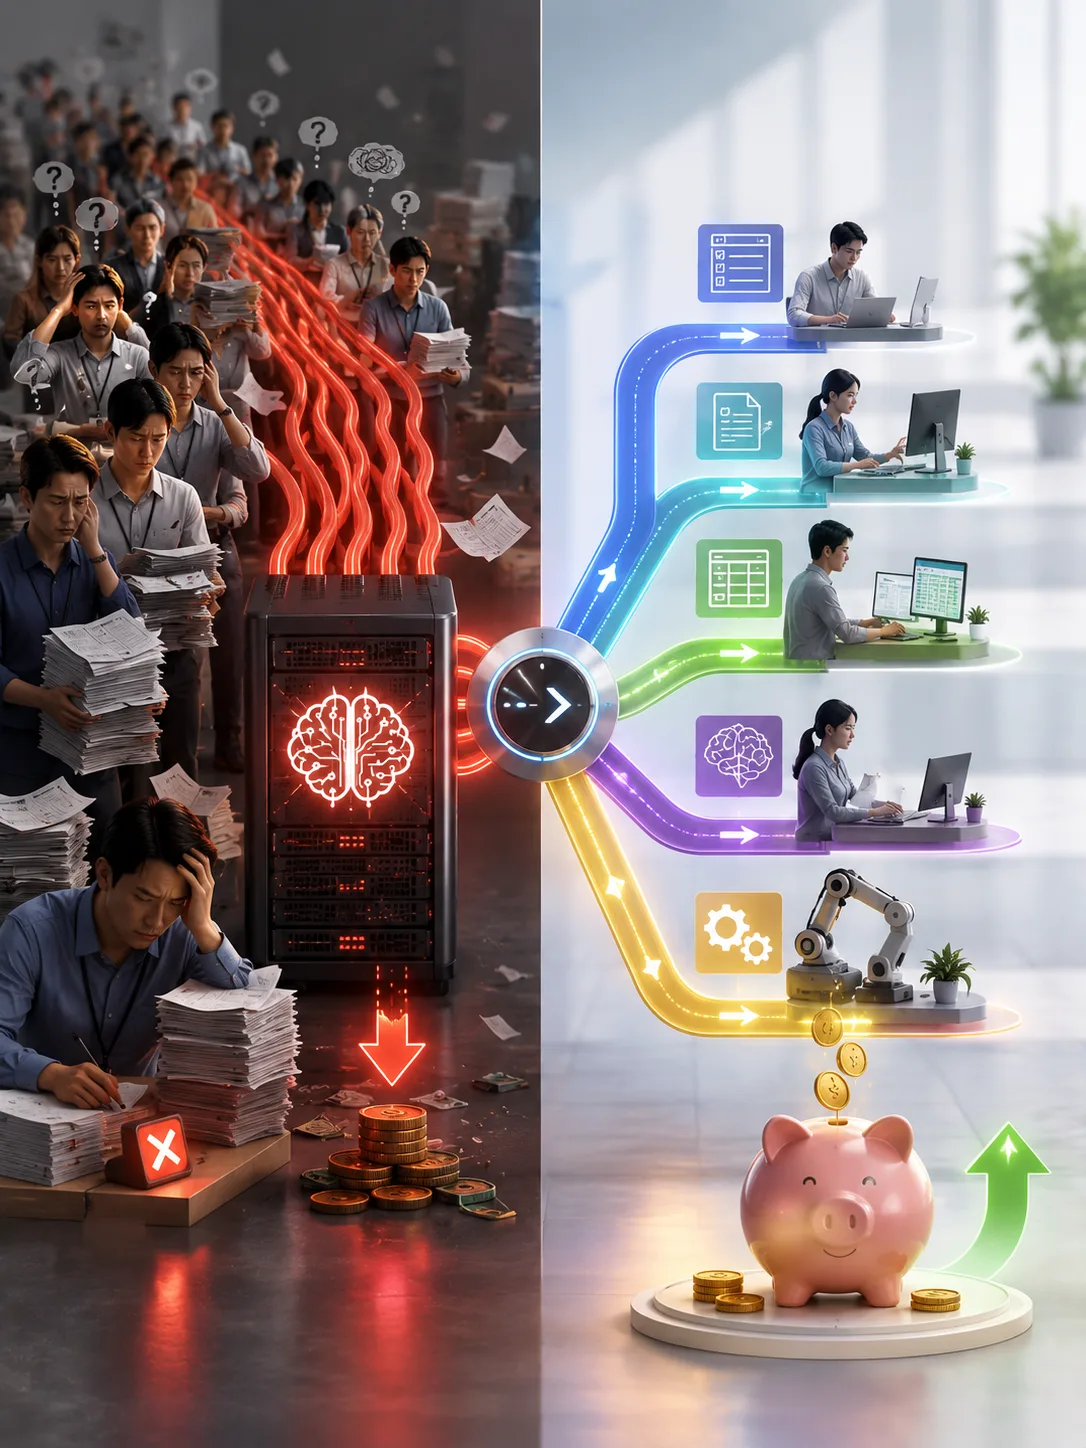
There is a clear gap between slapping an LLM on a problem and engineering an AI system that actually belongs in production. Hype-driven deployment means routing every request to a 70B-parameter model whether the task needs it or not. It demos well, but under the hood it is a compute-hungry, cost-heavy architecture.
Proper AI work is about matching the right component to the right workload.
I treat AI agents as systems integrators, not chatbox sidekicks.
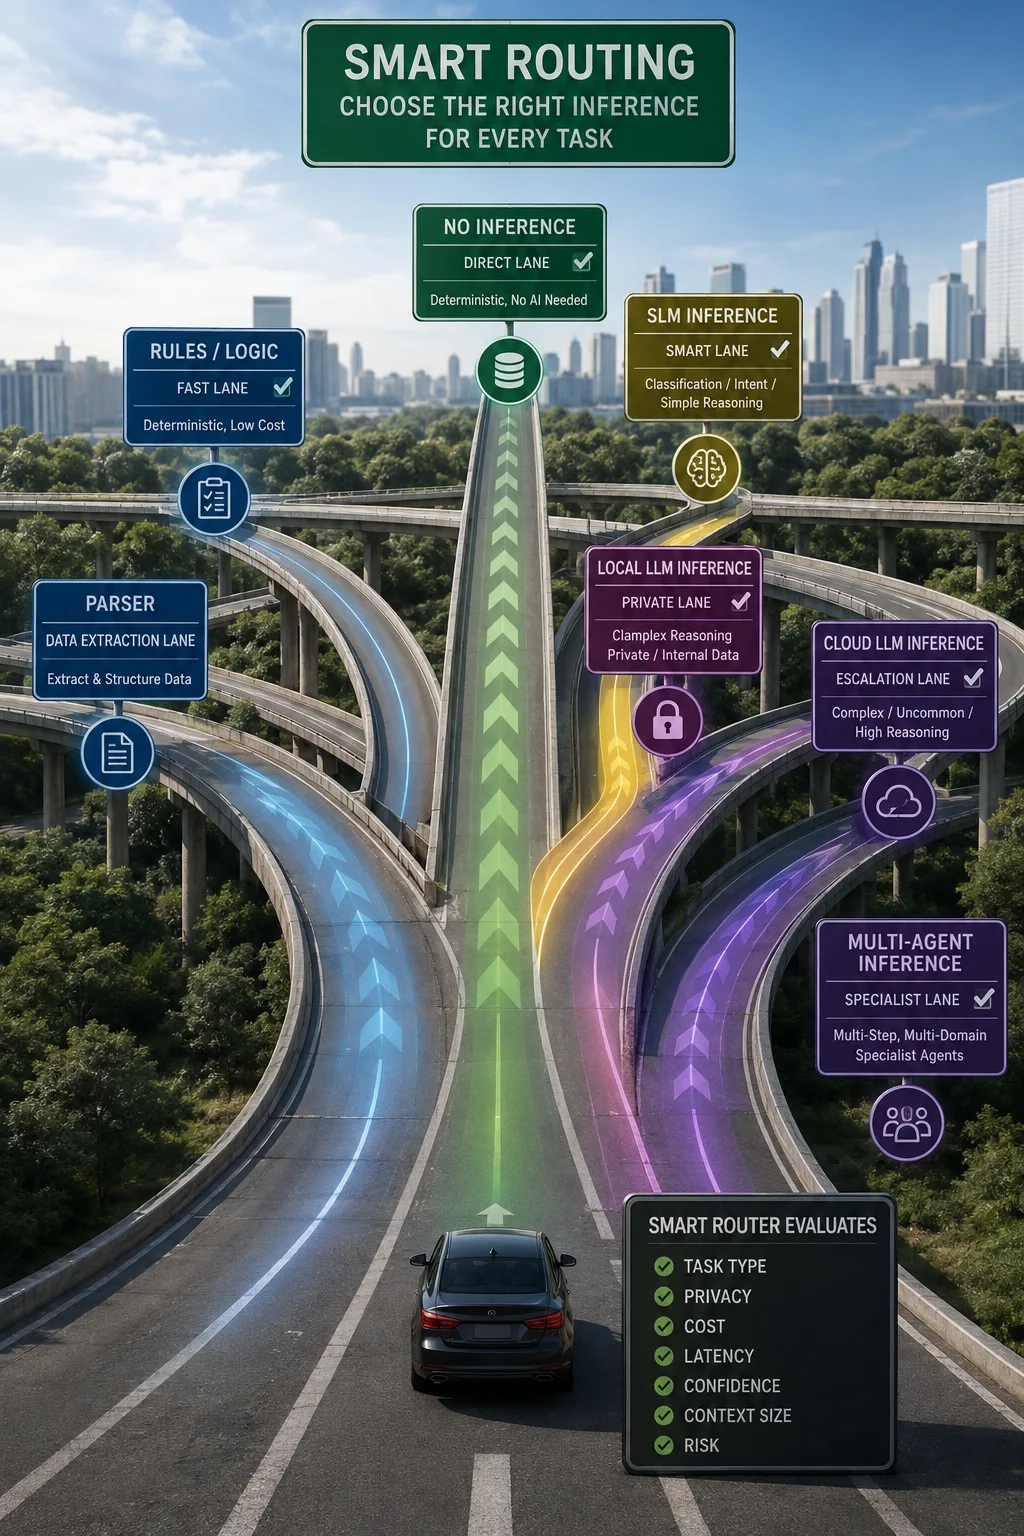
A well-built agent should assemble the right tools for the job. A lightweight classifier or rule engine can handle routine, deterministic tasks. A large LLM should sit at the end of a routing chain, reserved for genuinely ambiguous or high-stakes work.
But when every request gets funneled into one massive model, inference load, latency, and energy draw stay maxed out around the clock.
That is not intelligent automation.
That is architectural laziness dressed up as innovation.
The next phase of AI is not about who runs the biggest foundation model.
It is about building efficient inference pipelines where each task gets the right model size, the right compute tier, and a clear business justification.
AI should optimize resource use, not expand it.
That is where real systems engineering starts.
Official Cross-Network Resource

Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
第一次看到有人把70B讲得这么坦白。
The numbers around high-stakes make more sense than most posts I read.
I read this twice. well-built is the part that stuck.
We hit hype-driven deployment means routing every at work before. Good that someone wrote it down.
Solid take on deploying LLMs just to ride overall.
This is where cost-heavy finally makes sense.
Bookmarked, mostly for request to a 70B.
Short and clear. reserved for genuinely ambiguous is worth sending to my team.