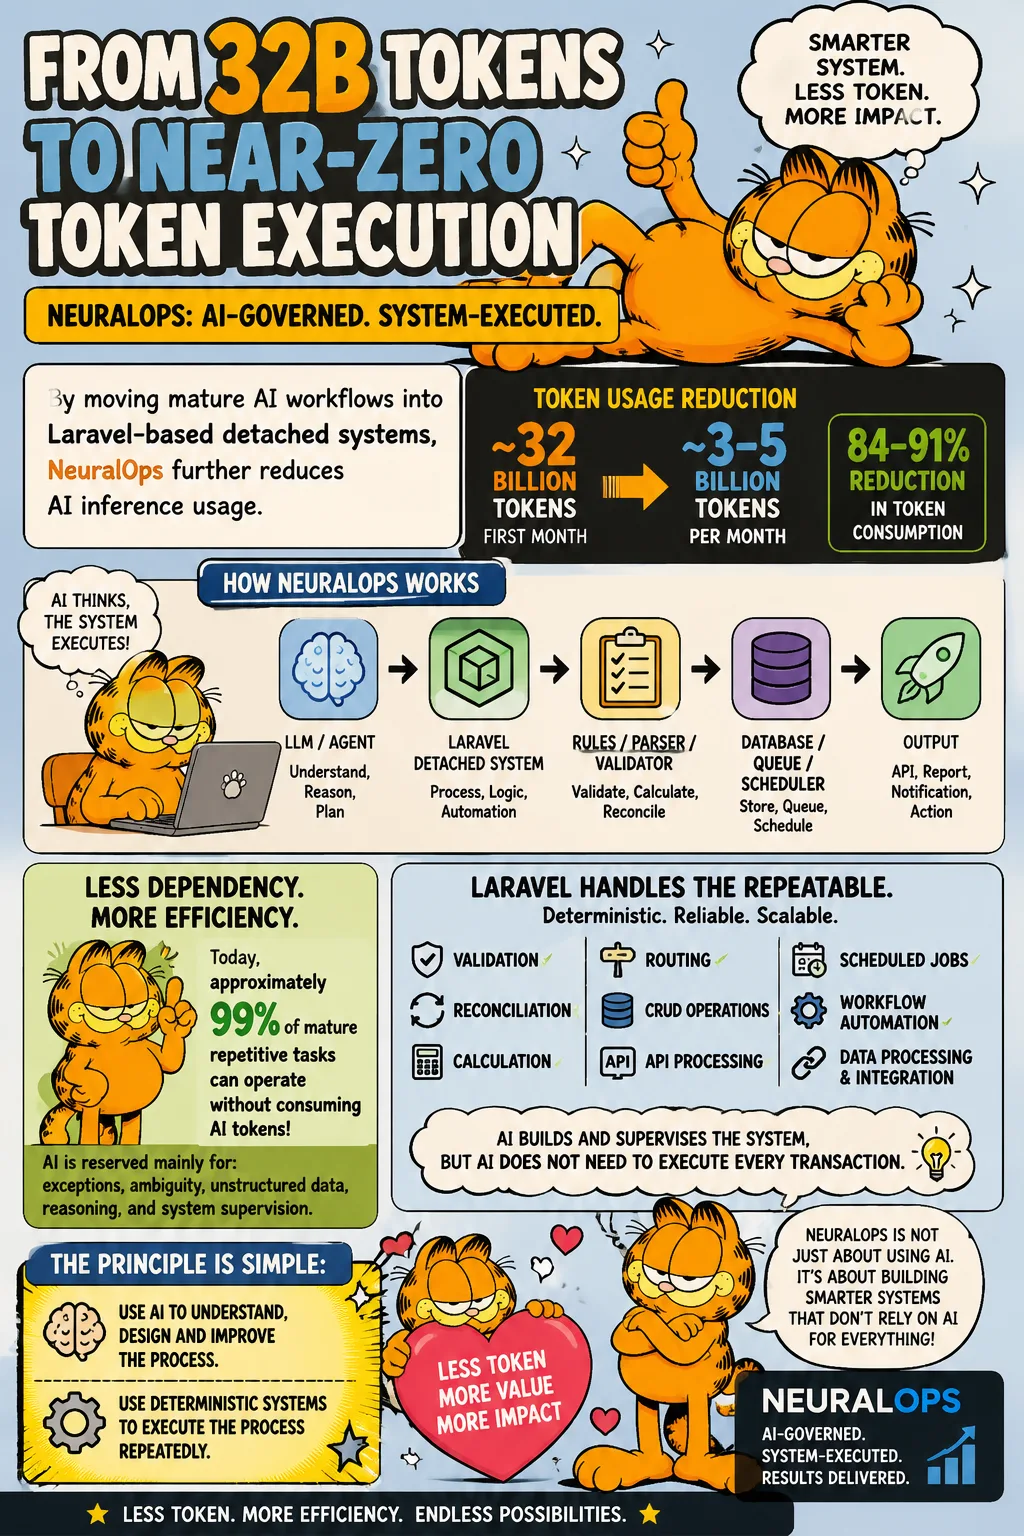
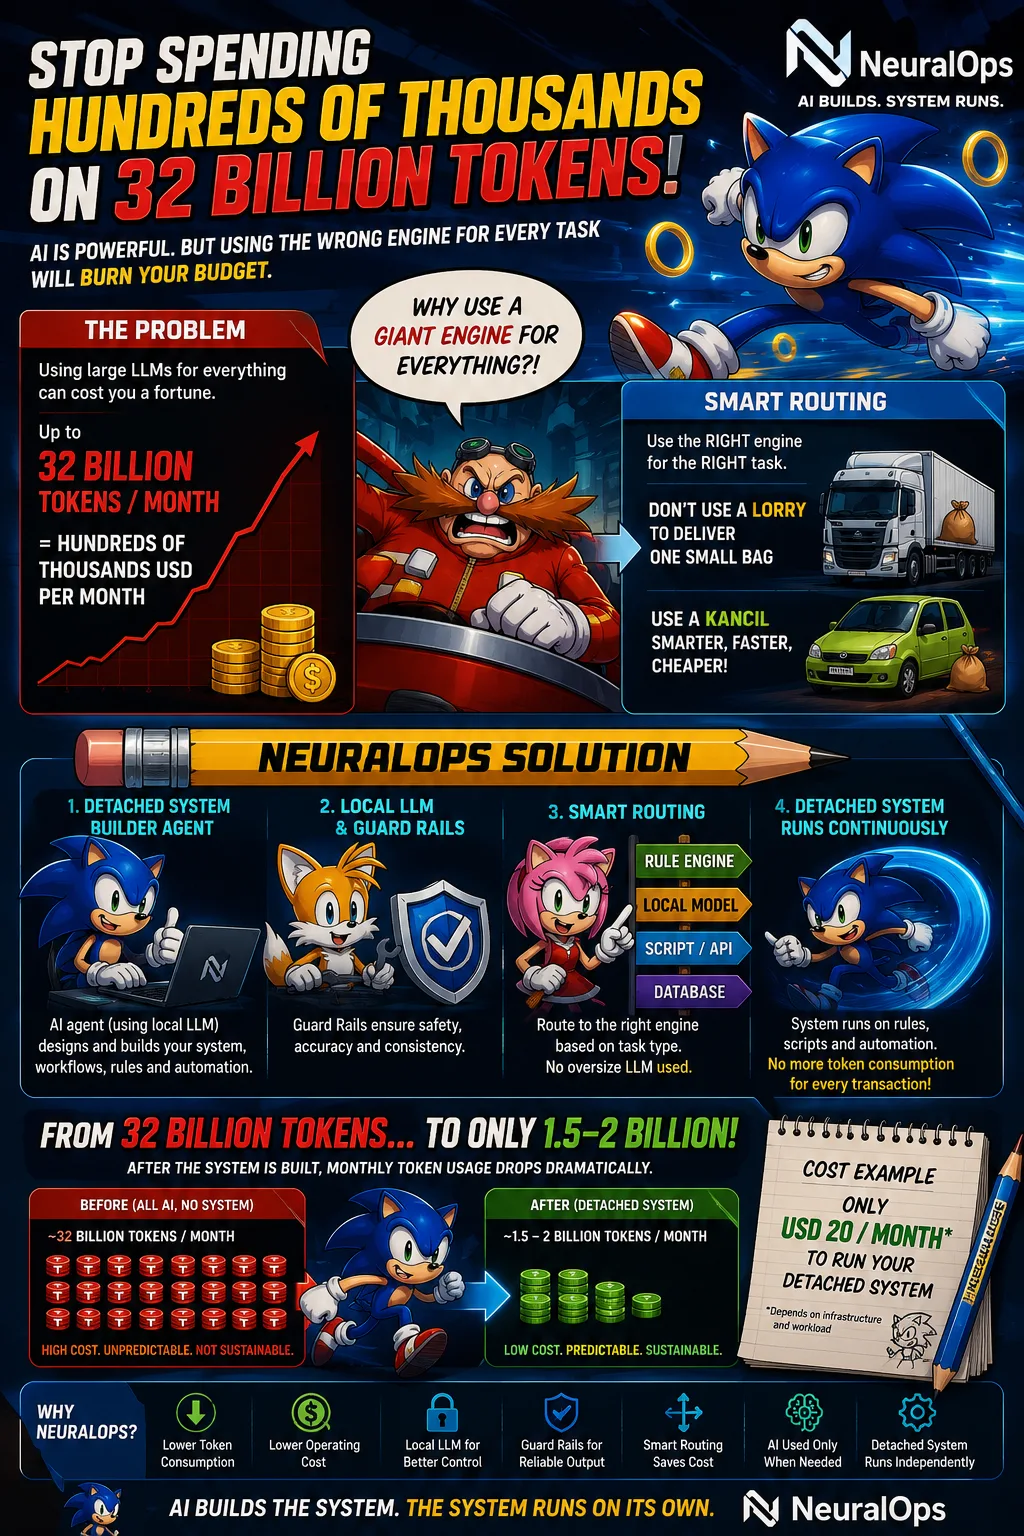
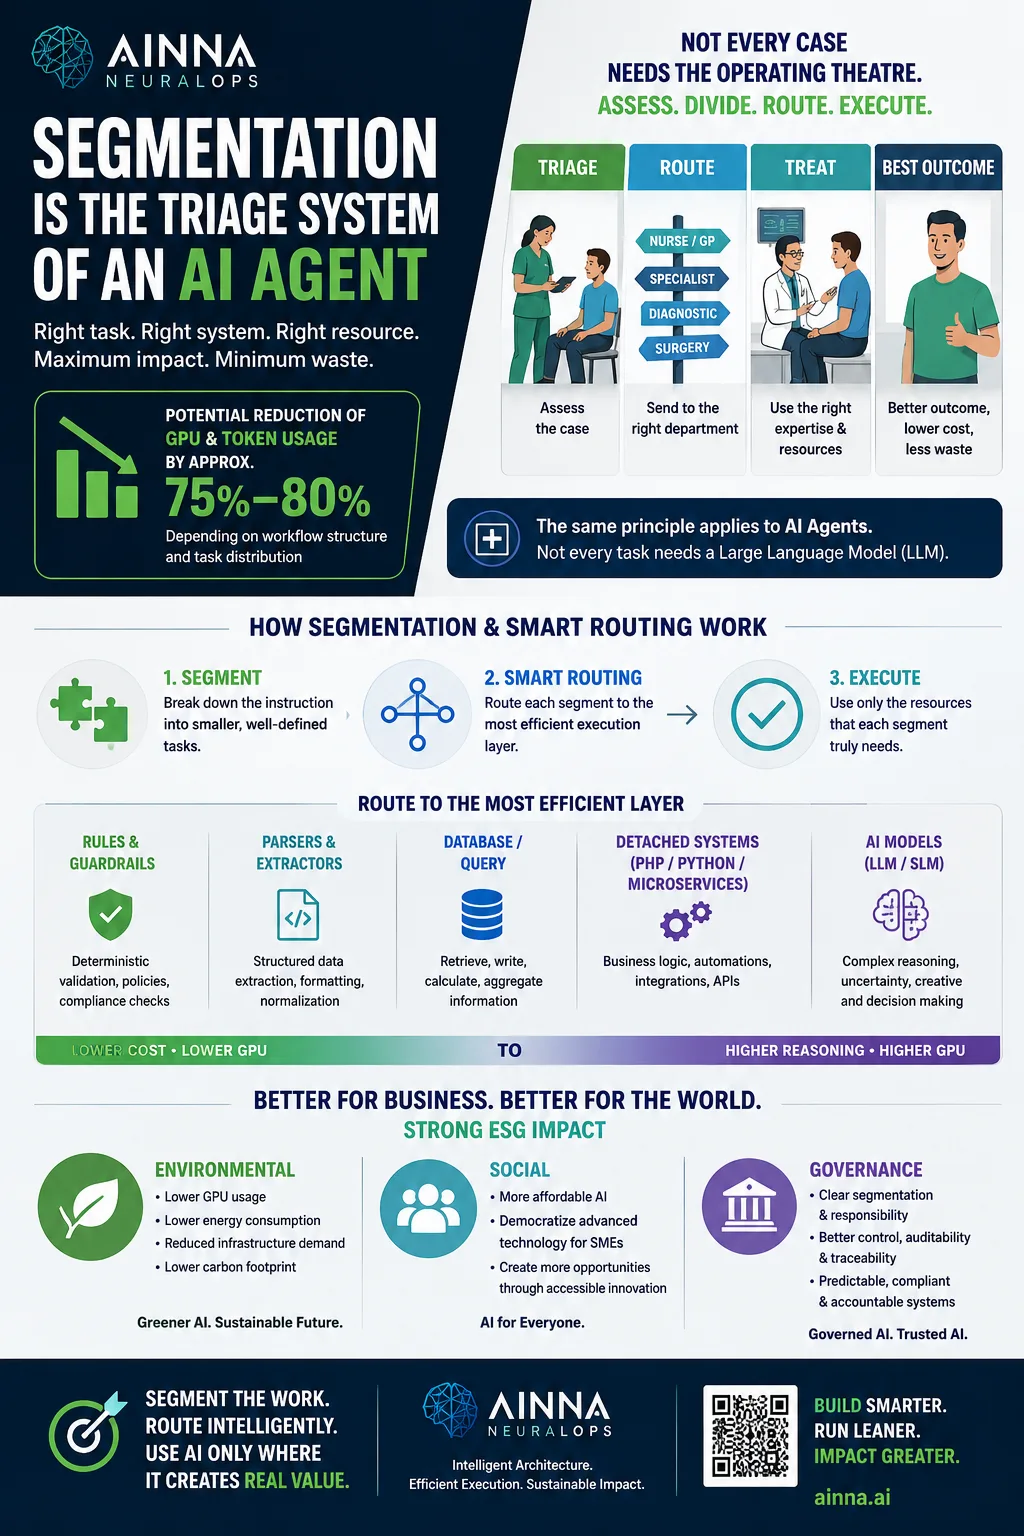
At AINNA, the fastest way we have found to burn through inference budget is to leave an LLM sitting in the hot path for work it already learned. We are changing that by moving stable AI workflows into Laravel-based detached execution systems, which lowers token burn without degrading capability.
After the migration, measured token usage on our NeuralOps architecture dropped from approximately 32 billion tokens in the first month to around 3–5 billion tokens per month. That is an estimated 84–91% reduction in token consumption across the same workflow footprint.
As more repetitive, structured pipelines are ported to deterministic Laravel backends, LLM dependency keeps falling. Today, approximately 99% of mature repetitive tasks can run without consuming any AI tokens. We reserve the model for the real edge cases: exceptions, ambiguity, unstructured data, reasoning, and system supervision.
The operating principle is simple:
Use neural models to understand the problem, design the flow, and refine it.
Use deterministic systems to execute that flow at scale, repeatedly.
This is how NeuralOps is moving from AI-heavy automation toward a more efficient AI-governed, system-executed architecture.

Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
Saya suka bagian 32 karena tidak terlalu teoretis.
Bagian 32 ini yang bikin saya berpikir ulang.
Still thinking about use neural models to understand.