The Real AI Race May Not Be About Bigger Models It May Be About Cheaper Intelligence
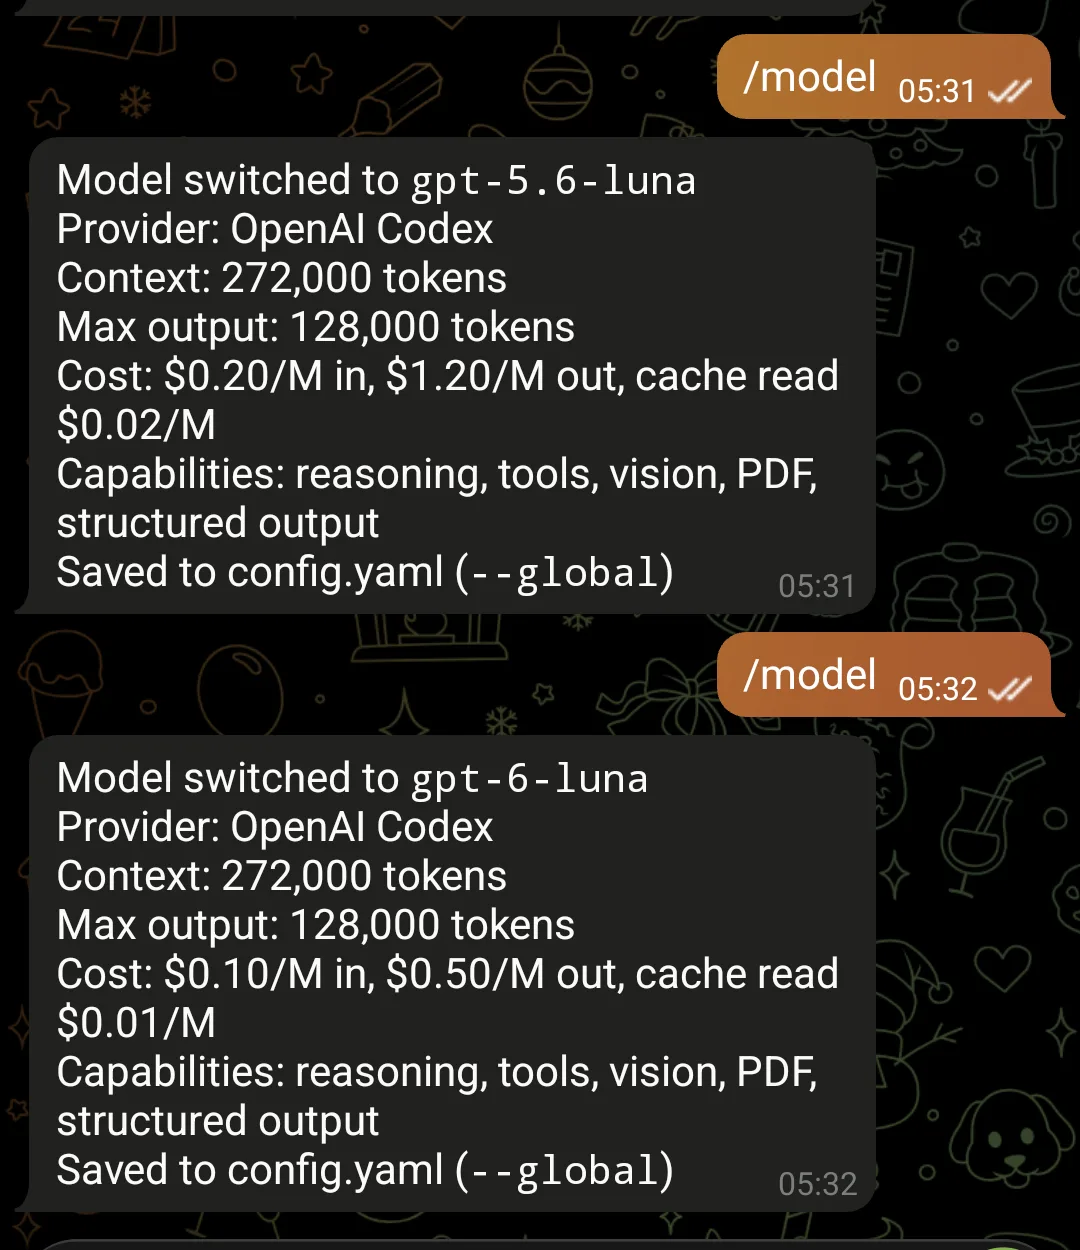
Looking at this comparison, the model name is not what holds my attention.
What holds my attention is the cost curve.
In this setup, pricing drops from roughly $0.20/M input and $1.20/M output to $0.10/M input and $0.50/M output, with the same stated context window and tool capabilities still on the table.
When numbers move like that, the engineering economics move with them.
From where I sit, this is one more solid argument for bulk-distilling local LLMs, and probably SLMs too.
Rather than renting expensive external inference forever, we can point increasingly optimized models at our own pipelines as teachers: generating training data, tightening workflows, extracting domain-specific reasoning patterns, and feeding all of it back into the local models we run.
The objective is not to ship the biggest model.
The objective is to ship a model that is optimized enough for the job it actually does.
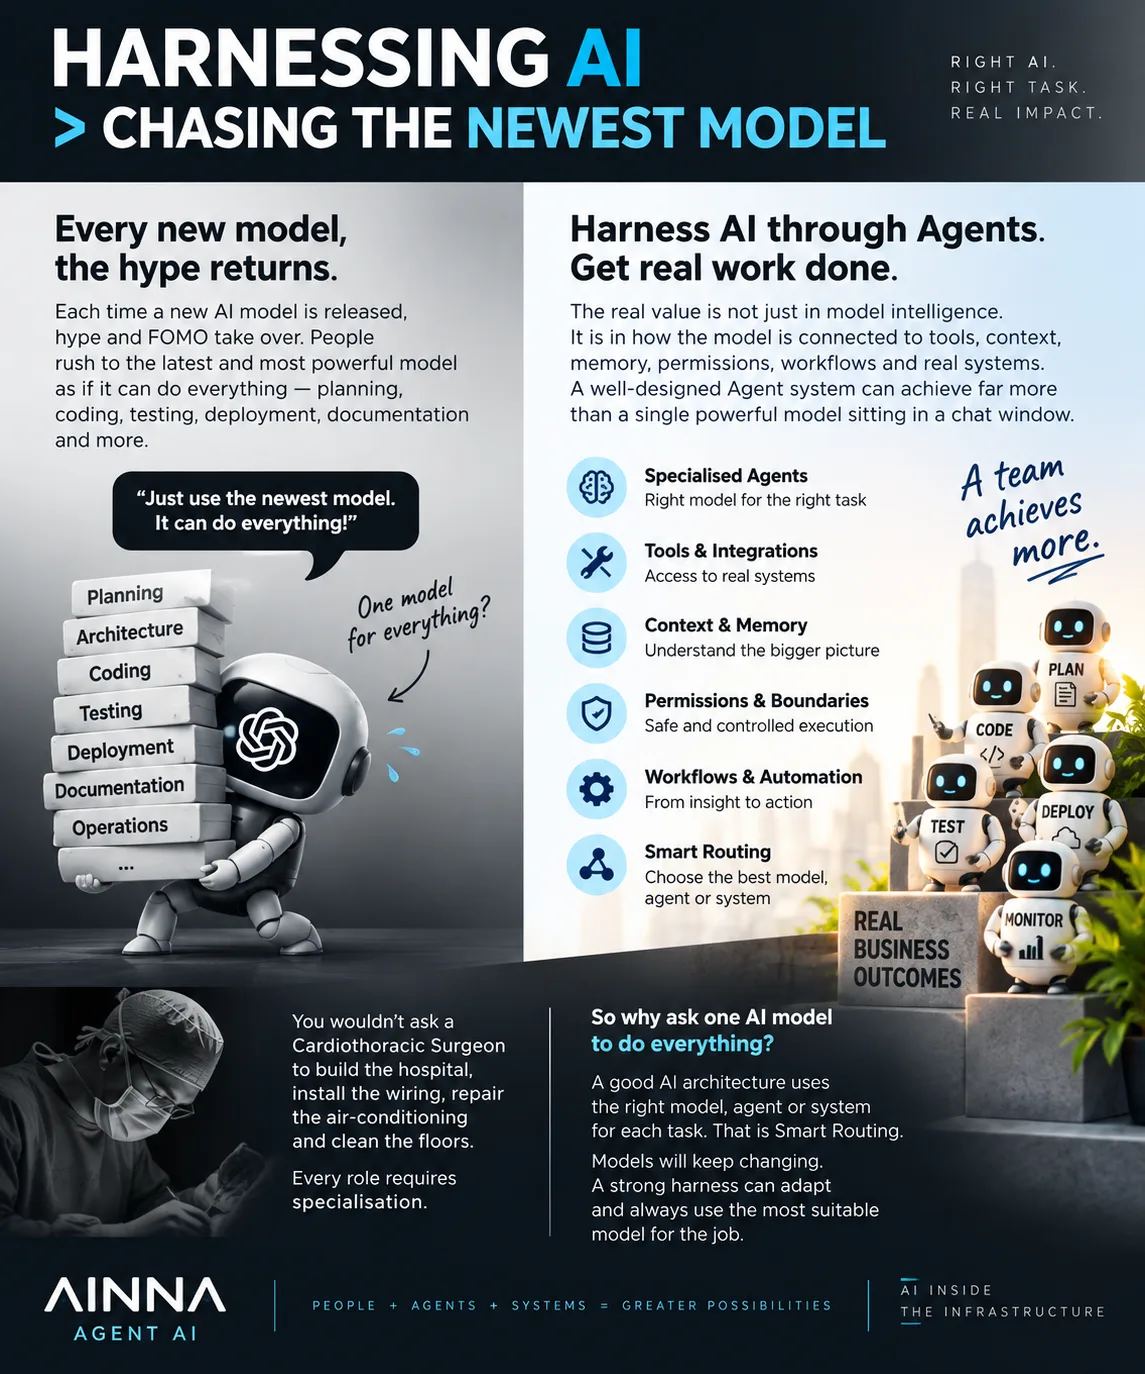
In practice, that means smaller models running accounting, inventory, operations, customer service, machinery control, document processing, or internal automation on our own hardware, and calling out to larger external models only when the workload genuinely demands it.
I want this pricing trend to keep going.
At least long enough for our local LLMs to mature to the point where they carry most of the workload on their own.
Build with optimized models. Distill what matters. Cut the dependency down over time.
Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
Si hay una continuación sobre esta parte, la leeré.
Lebih jelas daripada dek vendor yang saya terima pasal looking at this comparison.
Worth reading just for domain-specific.