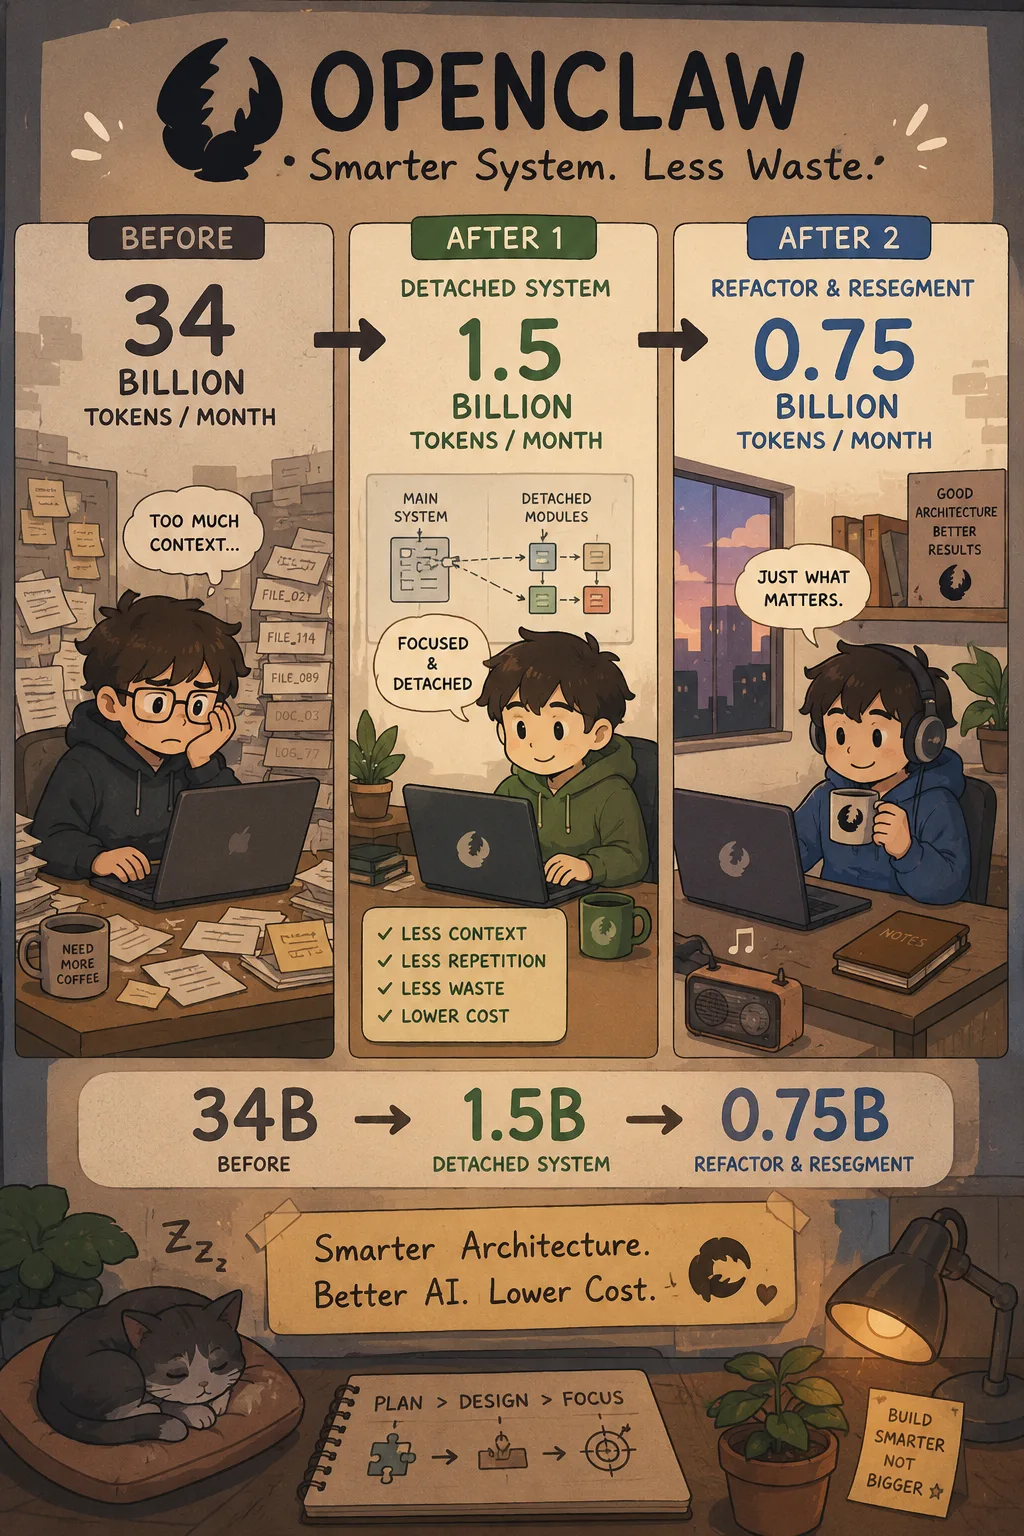
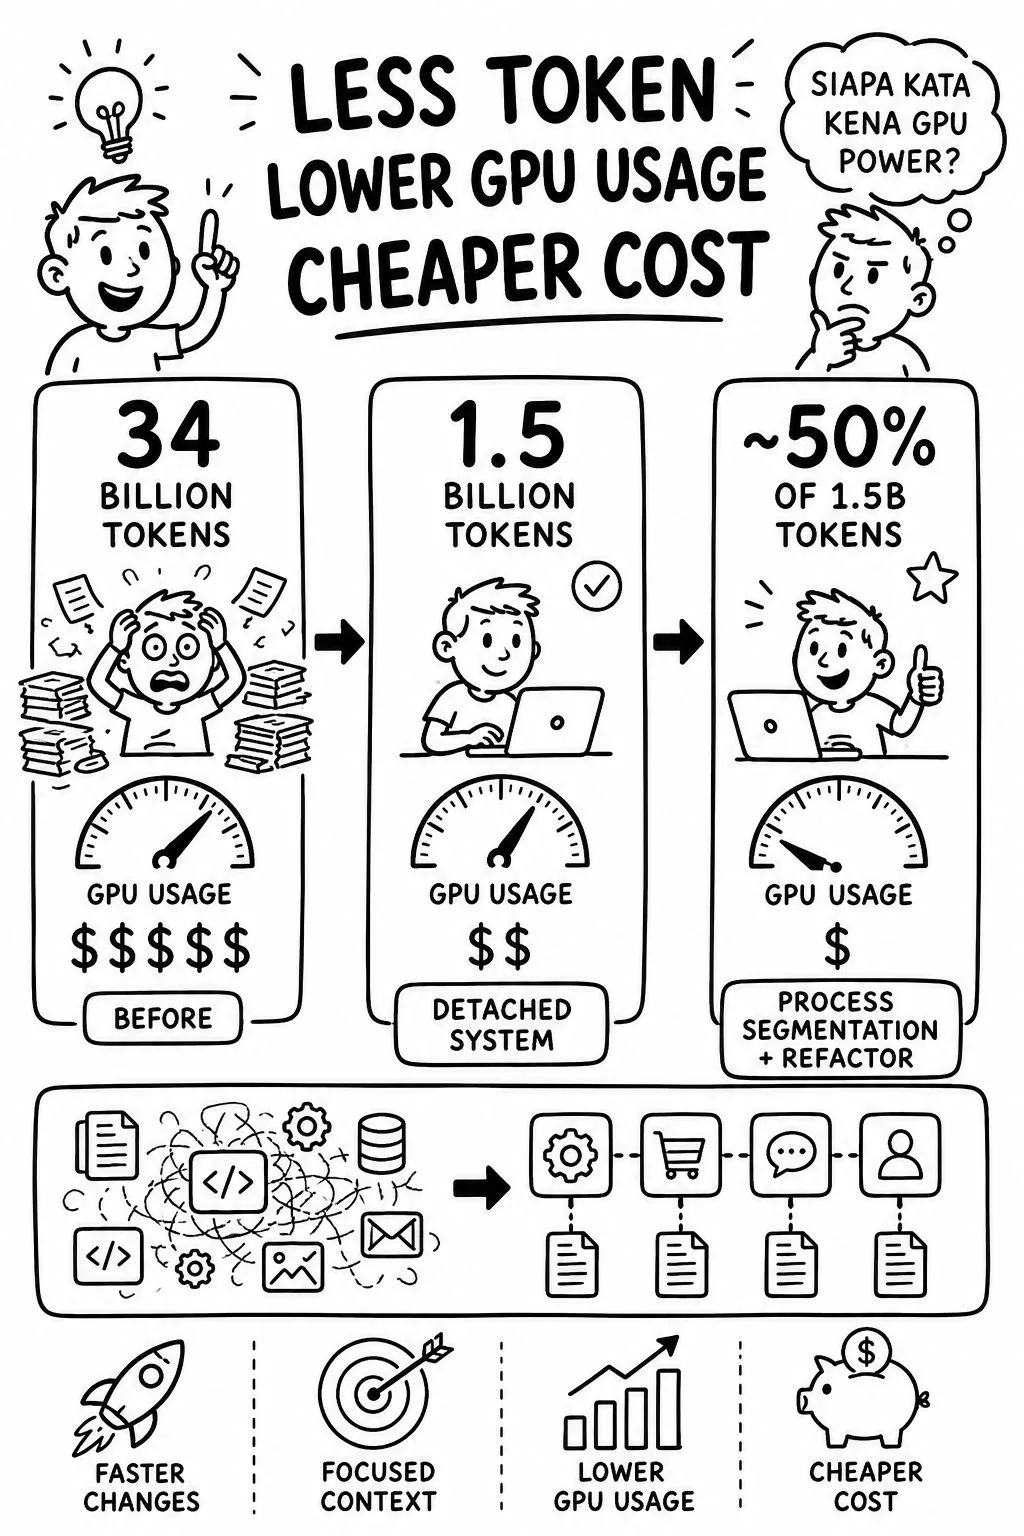
Since using OpenClaw, our token usage dropped from 34 billion tokens per month to 1.5 billion tokens per month through the Detached System approach.
Now, with Refactor and Resegment, we reduced it even further to around 750 million tokens per month.
The biggest lesson here is simple: optimization is not always about buying bigger GPUs or adding more compute power. Sometimes, the real breakthrough comes from redesigning how the system thinks, reads, and executes.
Before this, AI had to read too much context repeatedly just to make small changes. That created token waste, higher cost, slower execution, and unnecessary load on the system.
With Detached System, the workload became more focused. With Refactor and Resegment, each process became even more structured. The AI no longer needs to scan the whole system every time. It only works on the exact part that matters.
That is how we moved from:
34B → 1.5B → 750M tokens/month
Less context.
Less repetition.
Less waste.
Lower cost.
Faster execution.
For me, this proves one thing clearly: the future of AI efficiency is not only about stronger hardware. It is about smarter architecture.
Efficiency starts with system design.
#OpenClaw #AI #LLM #AIAgents #SystemArchitecture #TokenOptimization #SoftwareEngineering #AIEngineering #Efficiency
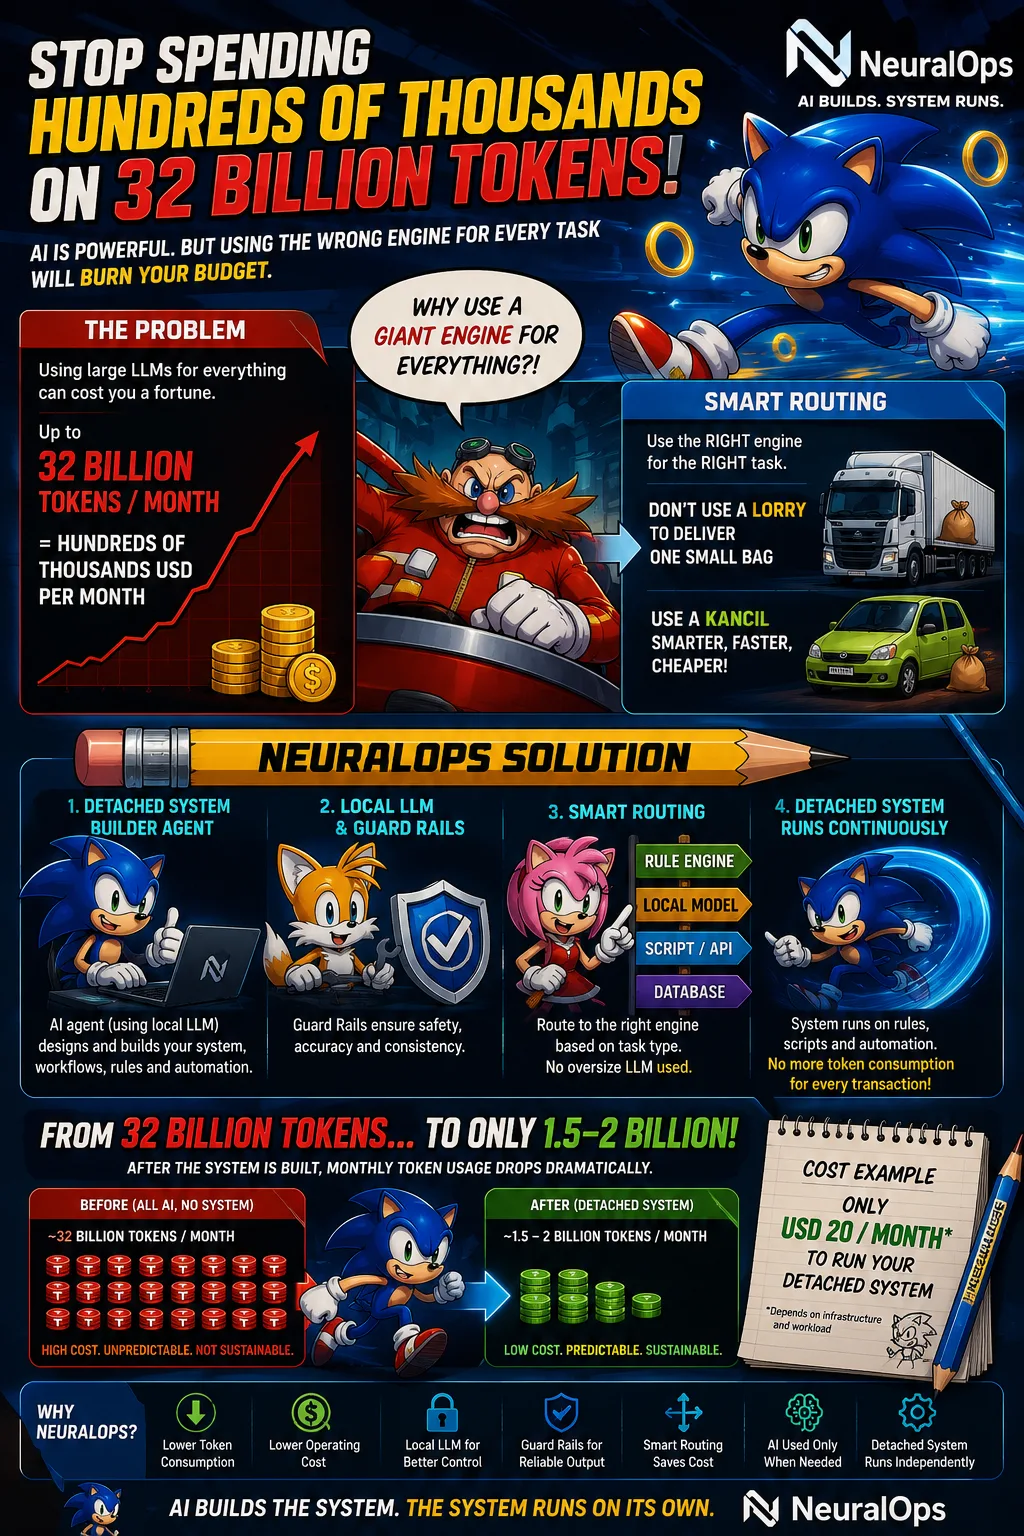
Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
简单直接。34就能说明问题。
34 के आँकड़े बाकी लेखों से ज़्यादा तर्कसंगत लगे।
अभी भी 34 के बारे में सोच रहा हूँ।
Honestly usage dropped from 34 billion caught me off guard.
The part on efficiency starts with system design is the bit I keep re-reading.
Baru kali ini ada yang bahas 34 dengan jujur.