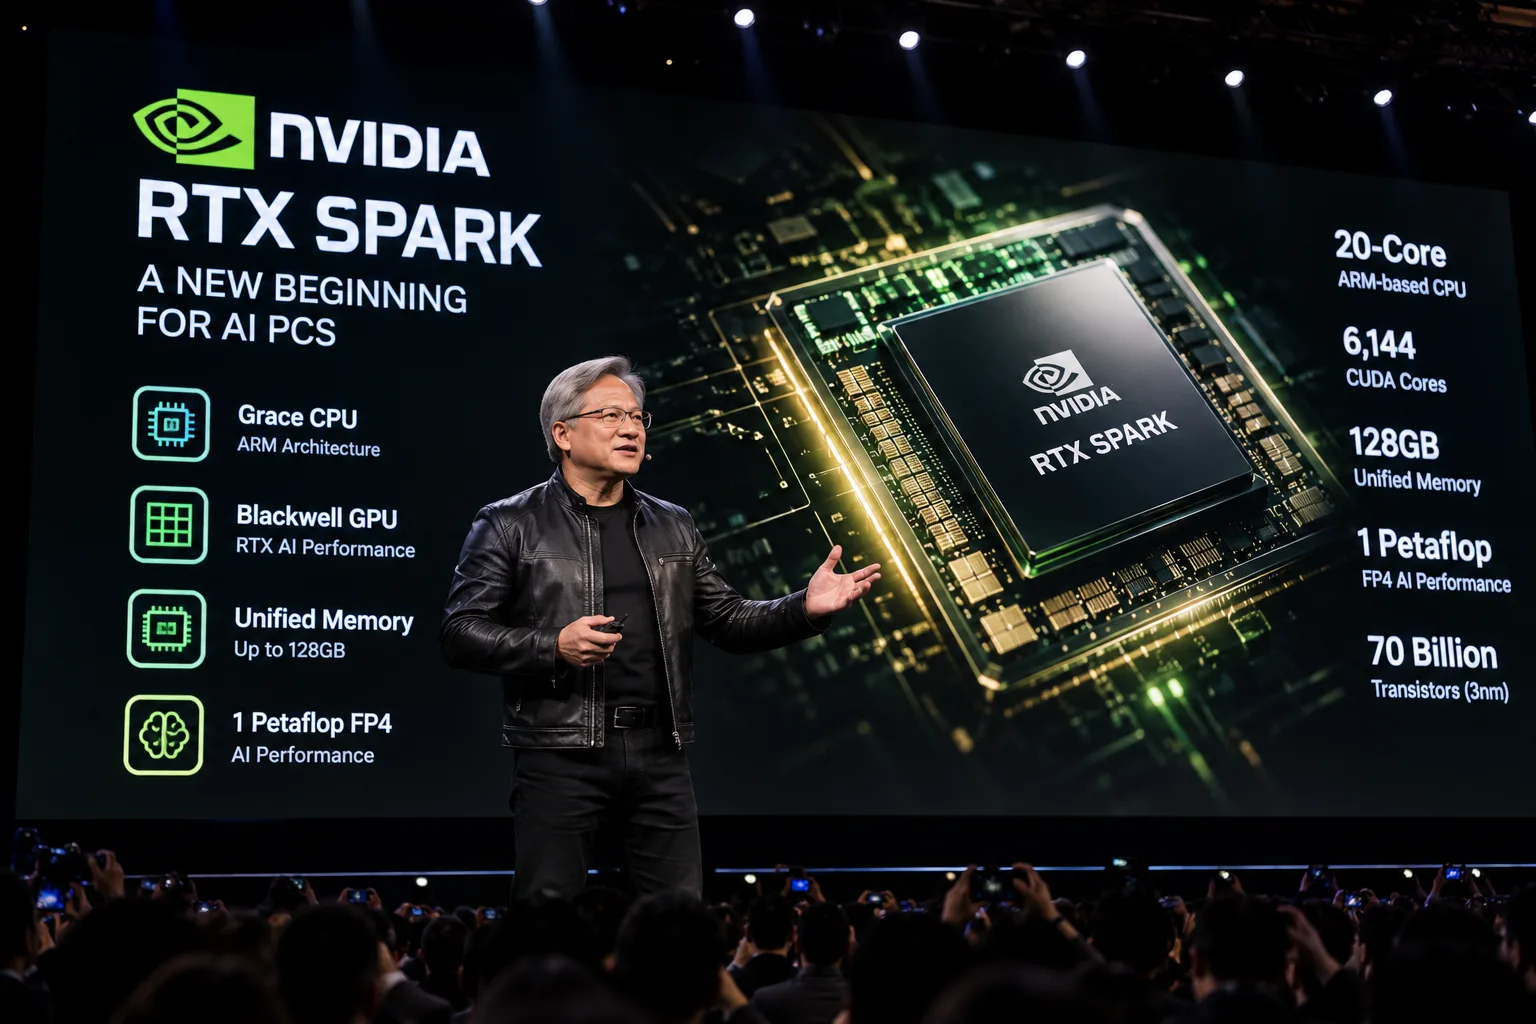
Jensen Huang's latest NVIDIA announcement reinforces a direction that matters directly to SME cost structures: AI computing is becoming smaller, more powerful and more energy-efficient.
At AINNA, that direction aligns with our long-term plan for NeuralOps-and, from my seat in finance and accounting, with a more disciplined approach to AI asset deployment, operating cost and measurable business value.
✅ WHERE WE ARE TODAY: COMPUTE EFFICIENCY AS A COST LEVER
The current server-based NeuralOps architecture is designed to do more with less computing power through:
⚡ Multi-Stage Smart Routing
⚡ Intelligent Caching
⚡ Specialised Parsers & Detached Execution
⚡ Local SLM/LLM Integration
⚡ Multi-Agent Orchestration (under development)
⚡ WebCLI & Telegram Access
🚀 WHERE WE ARE HEADING: A HARDWARE ROADMAP WITH FINANCIAL IMPLICATIONS
🟢 Phase 1 - NeuralOps Mini PC
Move NeuralOps from server infrastructure to dedicated PCB-based AI mini computers-shifting AI from a fixed server asset toward a more granular, deployable asset.
🔵 Phase 2 - Embedded NeuralOps
Integrate NeuralOps into increasingly compact ARM/NVIDIA AI computing modules, with smaller capital outlays per site and clearer cost allocation.
🟣 Phase 3 - NeuralOps on Future AI Silicon
Optimise our intelligence architecture for next-generation miniaturised chips, potentially through semiconductor partnerships-where useful life, maintenance cost and residual value become part of the commercial case.
The hardware roadmap is a future direction, not a claim of existing deployment-a distinction that matters in capital planning and reporting.
The business case for Malaysian SMEs is straightforward: SMEs, factories and industrial devices could run specialised AI agents locally, with minimal cloud dependency and a clearer link between compute cost and operational output.
We are not building our own semiconductor chip today; that is the right capital discipline for now.
We are building an intelligence architecture designed to become smaller as computing technology evolves-and, from a finance view, designed to scale cost more closely with actual use.
Maximum Intelligence. Minimum Compute. Clearer Cost Control.
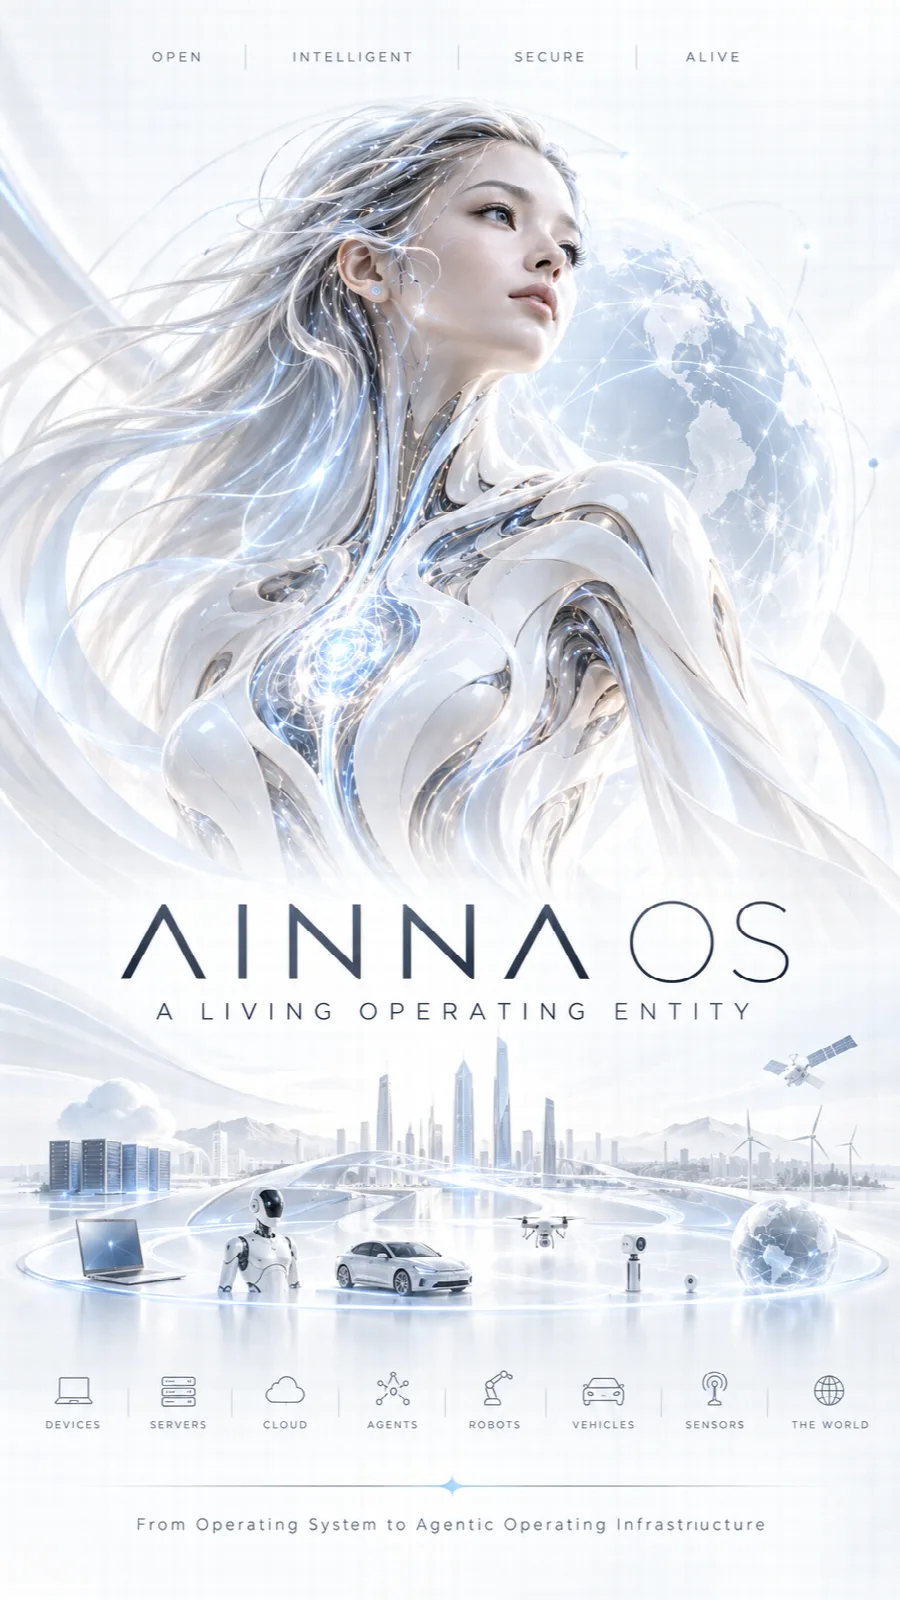
Today: Server-Based NeuralOps
Next: PCB Mini PC
Future: Embedded AI → Chip-Level Intelligence
#AINNA #NeuralOps #NVIDIA #JensenHuang #EdgeAI #AgenticAI #EmbeddedAI #DeepTech #AIInfrastructure #MalaysiaTech


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
أعجبني الجزء المتعلق بـ 2 لأنه عملي وليس نظريًا فقط.
The bit about operating cost and measurable business is what I keep coming back to.
The section on neuralOps mini PC move neuralops is the strongest part for me.
Bookmarked, mainly for COMPUTE EFFICIENCY AS A COST.
We hit 🔵 phase 2 - embedded at work before. Good that someone wrote it down.