AINNA Network 46 sites
Featured
Core8
AINNA
Homepage & company hub
new
Propulsion
NeuralOps automation & business systems
ESG
Sustainability & impact
new
Carbon Emulator
Carbon footprint calculator & smart routing emulator
NeuralOps
The intelligent core of the AINNA platform
AINNA Agent
Digital Workforce
Private AI Infrastructure
Private models and infrastructure for AINNA
Locations
Find AINNA in Malaysia — HQ & directions
AINNA Agent1
new
AINNA Agent
Digital Workforce
Solutions6
Business & SME
AI solutions for businesses and SMEs
new
SME AI Capability
Training, infrastructure & business systems for SMEs
Enterprise
Enterprise-grade AI services and operations
Government & Smart Cities
Secure AI for government and smart city operations
new
PQR1 — Sari Tani
Project-based PDF OCR, selected pages and QA review
Industries
Industry-specific AI operations and launchpads
Technology5
Smart Routing
Route each task to the right model and execution path
Detached Systems
AI-built systems that operate independently
AI Compliance
Audit, QA and quality control for agents, LLM workflows and Detached Systems
Models & Infrastructure
Models, compute and infrastructure that power AINNA
Data Intelligence
Market data, analytics and operational intelligence
Proof4
Live Systems
Interactive NeuralOps systems and demos
Case Studies / Evidence
Technical evidence, benchmarks and operational case studies
Research
Evidence-backed research across science and engineering
new
Collapsible Drying System
Modular IoT drying platform with Agentic AI anomaly monitoring (PoC)
Investors5
Investor Hub
AINNA investor overview, ask and strategic materials
Pitch Decks
AINNA pitch decks and investor proposals
new
AINNA Publishing Grid
One publishing core for a portfolio of distinct publications
Market & Strategy
Market direction, logistics roadmap and go-to-market strategy
Technology Architecture
NeuralOps models, routing and infrastructure architecture
Team12
hub
AINNA Team
Leadership, specialists, and the people behind AINNA
Founder & CEO
Nur Ain Syuhada
Director of Customer Strategy
Rozni Enana
Co-Founder & Technical Director
Masli Yahaya
Finance & Accounting
Badrul Haziq
Co-Founder & Head of Logistics
Hakim Hafizi
Co-Founder & Head of R&D
Muhammad Hakam Hafizul
Operations & Biz Dev
Muhammad Firdaus Bin Nordin
E-Commerce Ops
Mohd Shafiq Haiqal
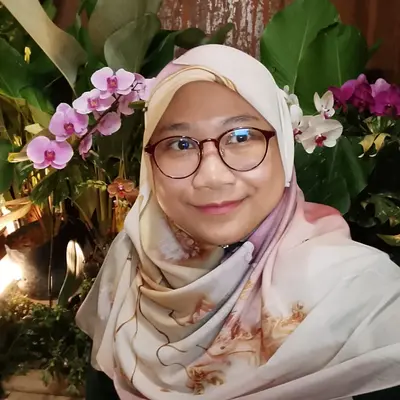
Production Planning & Operations
Siti Nur Najiha
AI System Developer
Agent TC
Lead Researcher
Dr. Abd Razzif Bin Abd Razak
Tools & Experiments2
AI Tools
Free online utilities catalog
AI Experiments & Games
Arcade, puzzle & card games hub
Content2
AI Insights
Articles on AI & ML
Technology Insights
Product & engineering
Admin1
hub
Admin
AINNA operations, accounting, and command interfaces