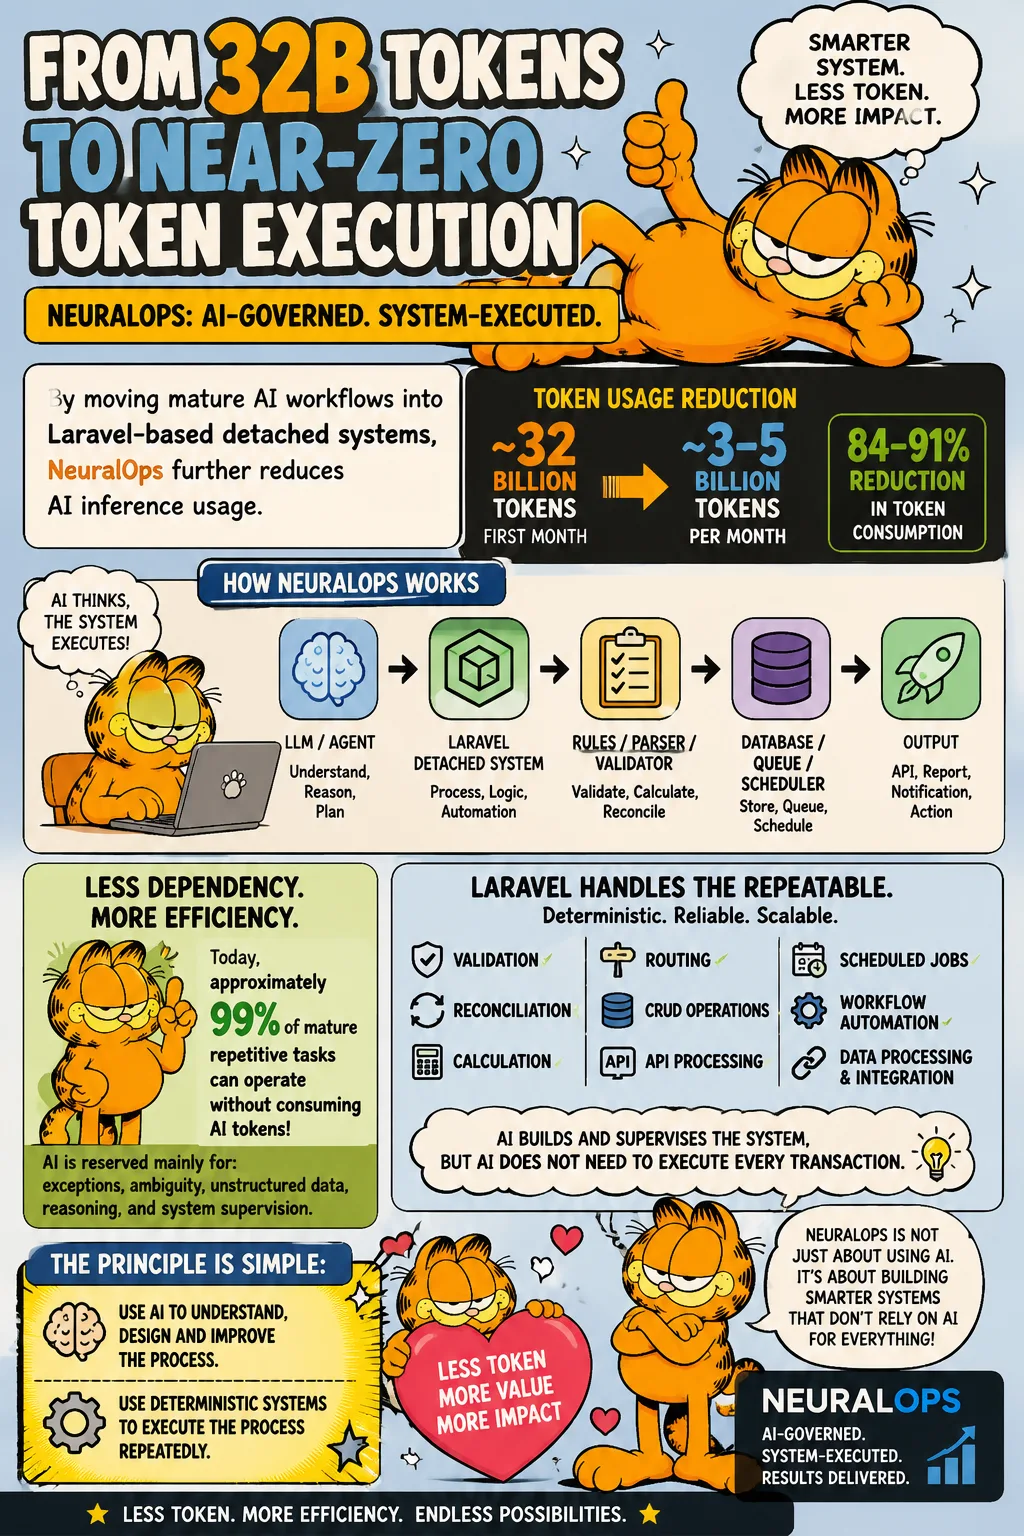
By moving mature AI workflows into Laravel-based detached systems, NeuralOps further reduces AI inference usage.
Based on our current architecture, token usage has dropped from approximately 32 billion tokens in the first month to around 3–5 billion tokens per month, representing an estimated 84–91% reduction in token consumption.
As more repetitive and structured workflows are migrated into Laravel-based detached systems, the dependency on LLM inference continues to fall. Today, approximately 99% of mature repetitive tasks can operate without consuming AI tokens, with AI reserved mainly for exceptions, ambiguity, unstructured data, reasoning, and system supervision.
The principle is simple:
Use AI to understand, design and improve the process.
Use deterministic systems to execute the process repeatedly.
This is how NeuralOps moves from AI-heavy automation toward a more efficient AI-governed, system-executed architecture.
Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
ถ้ามี32ต่อ ผมจะอ่านแน่นอน
First piece I have read that treats use deterministic systems to execute honestly.
Clearer than the vendor decks I get about an estimated 8 84.
The numbers around system-executed architecture make more sense than most posts I read.
الجزء المتعلق بـ 32 جعلني أفكر مطولًا.
Honestly, an estimated 84–91% 91% surprised me.